Yu Lu

Yu Lu

Postdoctoral Researcher

Zhejiang University
Email: aniki.yulu [at] gmail.com

Yu Lu (路雨) is a Postdoctoral Researcher at Zhejiang University, where he leads a research team working on video and image generative models. He received his Ph.D. from the University of Technology Sydney (UTS) under the supervision of Prof. Yi Yang. He has also worked at WeChat (Tencent), Kuaishou, Tencent AI Lab, and Baidu Research.

His research focuses on Interactive Video Intelligence: building AI systems that can understand and remember dynamic visual worlds, imagine how they evolve, and learn to act in them.


News

  • [Oct 2026] I will serve as an Area Chair for ICLR 2027 and ICML 2027.
  • [Sep 2026] SpecLoR accepted by NeurIPS 2026!
  • [Jul 2026] SAMA accepted by ECCV 2026! Paper, code, and pretrained model are released.
  • [Jul 2026] We organized the Long Video Generation Workshop at ICML 2026.
  • [Jun 2026] We released FadeMem for memory-based autoregressive long video diffusion.
  • [Feb 2026] CoLoGen accepted by CVPR 2026!
  • [Sep 2025] FlexSelect and ICEdit accepted by NeurIPS 2025!
  • [Jul 2025] We released FreeLong++ for training-free long video generation, extending videos up to 8× longer!
  • [Feb 2025] HarmonySet accepted by CVPR 2025!
  • [Dec 2024] Paper on video-text retrieval with unlabeled videos accepted by TIP!
  • [Sep 2024] Two papers (FreeLong and AMP) accepted by NeurIPS 2024!
  • [Sep 2024] Successfully defended my Ph.D. thesis "Zero-shot Natural Language-Driven Video Analysis and Synthesis".
  • [Jan 2024] Paper on zero-shot video grounding accepted by TIP!

Selected Publications

* equal contribution  ·  ✉ corresponding author
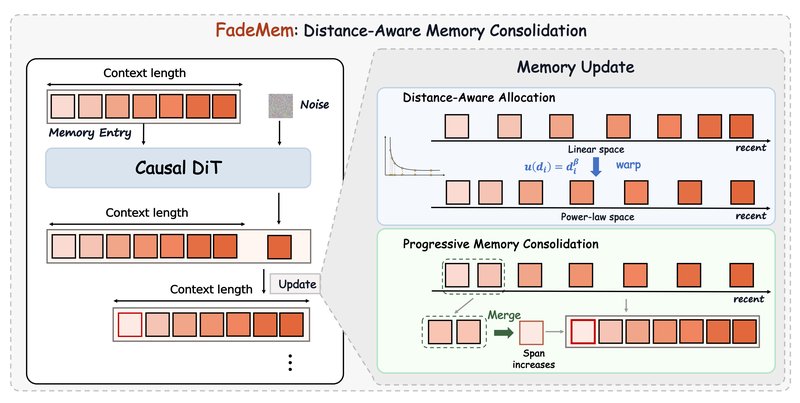
FadeMem

FadeMem: Distance-Aware Memory Consolidation for Autoregressive Video Diffusion
Yu Lu, Junjie Yang, Piotr Koniusz, Yuxin Song, Yi Yang
arXiv
[Paper] [Project]

SpecLoR

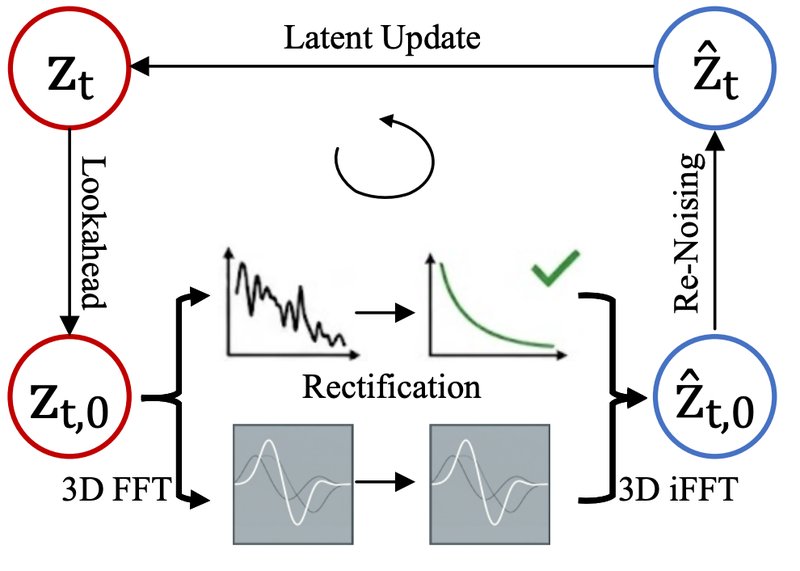
SpecLoR: Spectral Lookahead Rectification for Motion-Coherent Text-to-Video Generation
Xu Zhang, Yu Lu, Ruijie Quan, Zhaozheng Chen, Bohan Wang, Yi Yang
NeurIPS 2026
[Paper] [Project]

SAMA

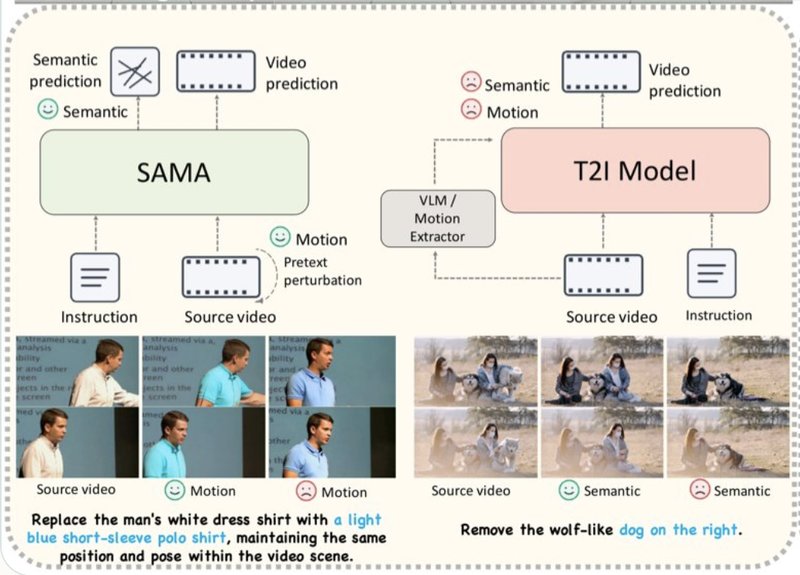
SAMA: Factorized Semantic Anchoring and Motion Alignment for Instruction-Guided Video Editing
Xinyao Zhang, Wenkai Dong, Yuxin Song, Bo Fang, Qi Zhang, Jing Wang, Fan Chen, Hui Zhang, Haocheng Feng, Yu Lu✉, Hang Zhou, Chun Yuan, Jingdong Wang
ECCV 2026
[Paper] [Project]

CoLoGen

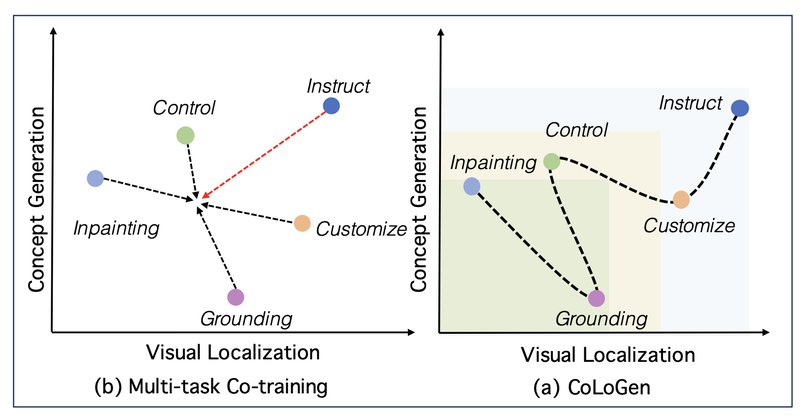
CoLoGen: Progressive Learning of Concept–Localization Duality for Unified Image Generation
Yuxin Song, Yu Lu✉, Haoyuan Sun, Huanjin Yao, Fanglong Liu, Yifan Sun, Haocheng Feng, Hang Zhou, Jingdong Wang
CVPR 2026
[Paper]
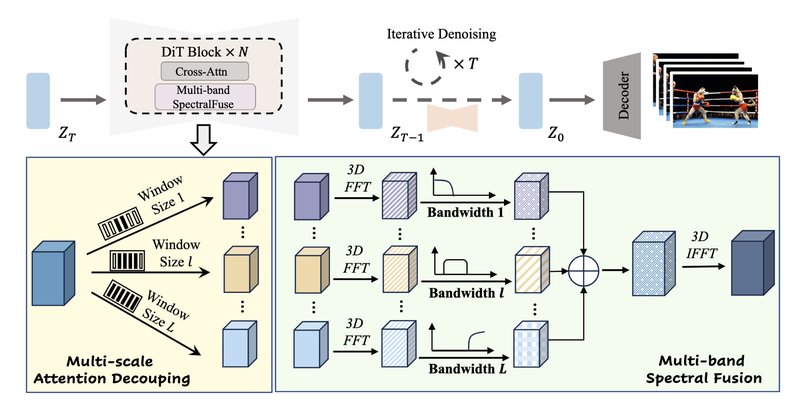
FreeLong++

FreeLong++: Training-Free Long Video Generation via Multi-band SpectralFusion
Yu Lu, Yi Yang
arXiv
[Paper] [Project]

FlexSelect

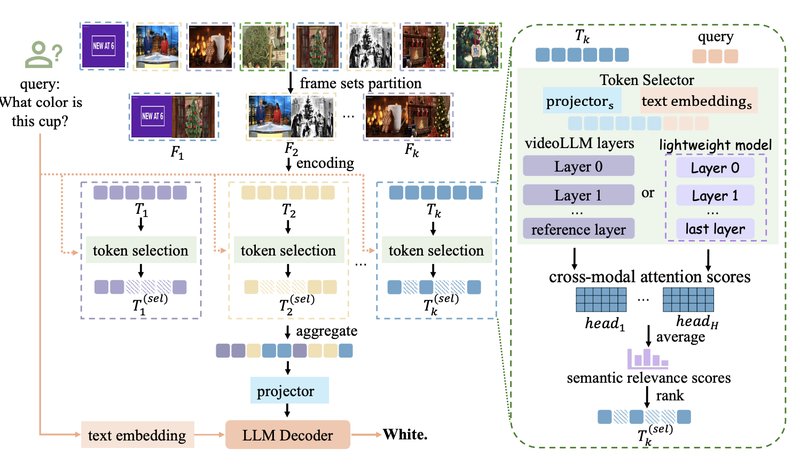
FlexSelect: Flexible Token Selection for Efficient Long Video Understanding
Yunzhu Zhang*, Yu Lu*, Tianyi Wang, Fengyun Rao, Yi Yang, Linchao Zhu
NeurIPS 2025
[Paper] [Project]

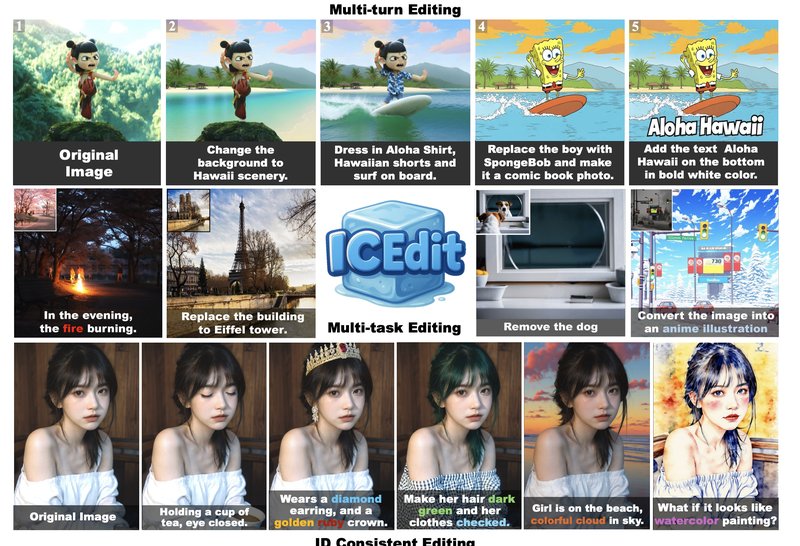
In-Context Edit

In-Context Edit: Enabling Instructional Image Editing with In-Context Generation in Large Scale Diffusion Transformer
Zechuan Zhang, Ji Xie, Yu Lu, Zongxin Yang, Yi Yang
NeurIPS 2025
[Paper] [Project]

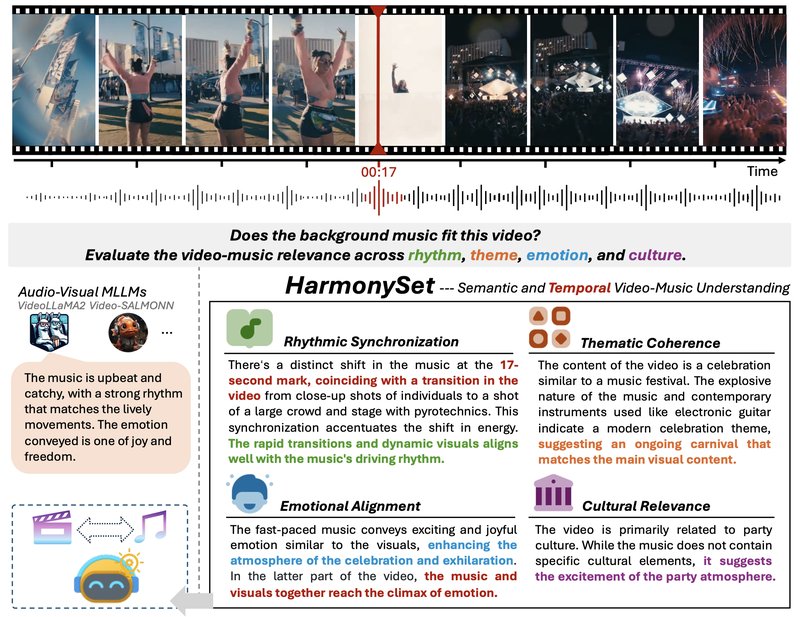
HarmonySet

HarmonySet: A Comprehensive Dataset for Understanding Video-Music Semantic Alignment and Temporal Synchronization
Zitang Zhou, Ke Mei, Yu Lu✉, Tianyi Wang, Fengyun Rao
CVPR 2025
[Paper] [Project]

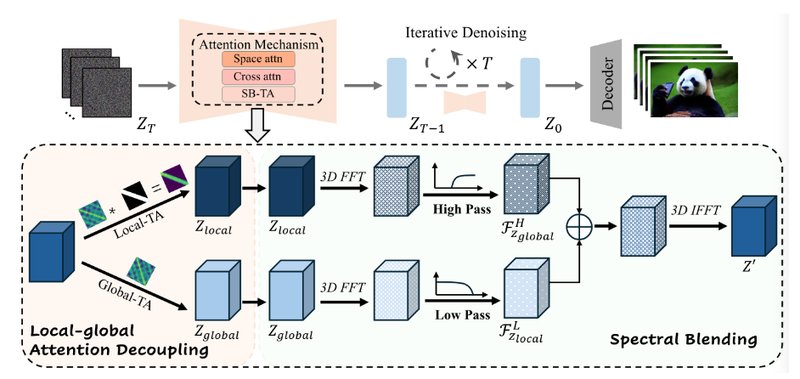
FreeLong

FreeLong: Training-Free Long Video Generation with SpectralBlend Temporal Attention
Yu Lu, Yuanzhi Liang, Linchao Zhu, Yi Yang
NeurIPS 2024
[Paper] [Project] [Code]

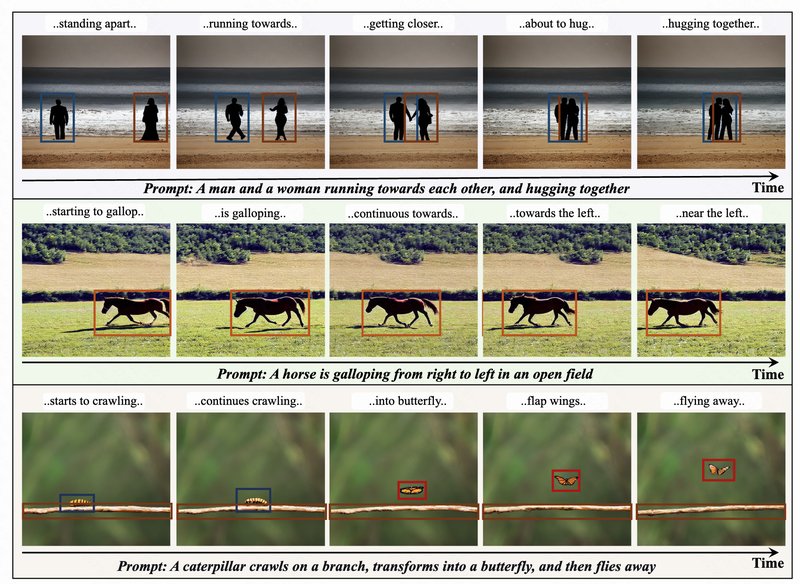
FlowZero

FlowZero: Zero-Shot Text-to-Video Synthesis with LLM-Driven Dynamic Scene Syntax
Yu Lu, Linchao Zhu, Hehe Fan, Yi Yang
arXiv
[Paper] [Project] [Code]

Zero-shot Video Grounding

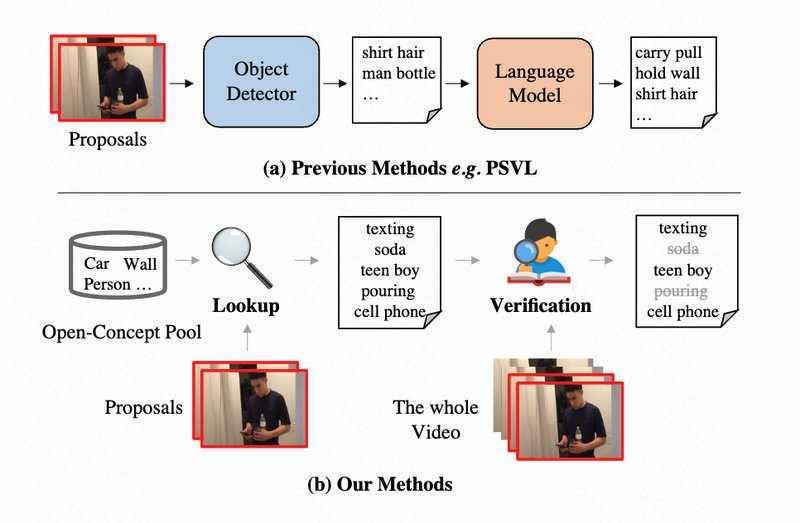
Zero-shot Video Grounding with Pseudo Query Lookup and Verification
Yu Lu, Ruijie Quan, Linchao Zhu, Yi Yang
IEEE Transactions on Image Processing (TIP), 2024
[Paper]
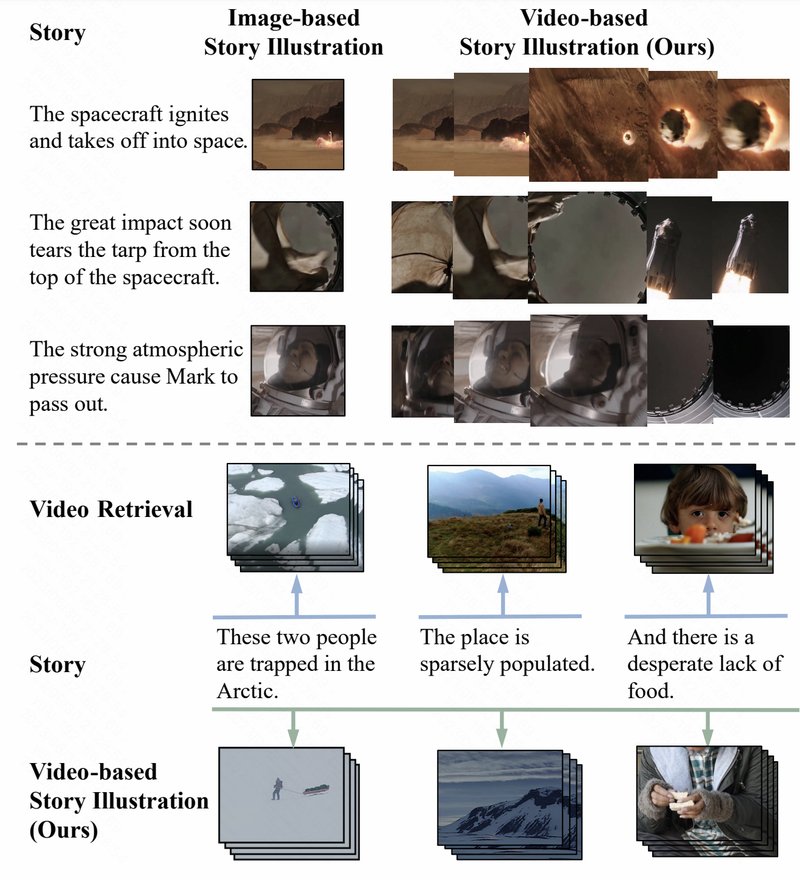
Show Me a Video

Show Me a Video: A Large-Scale Narrated Video Dataset for Coherent Story Illustration
Yu Lu, Feiyue Ni, Haofan Wang, Xiaofeng Guo, Linchao Zhu, Zongxin Yang, Ruihua Song, Lele Cheng, Yi Yang
IEEE Transactions on Multimedia (TMM), 2023
[Paper] [Project]

CRIS

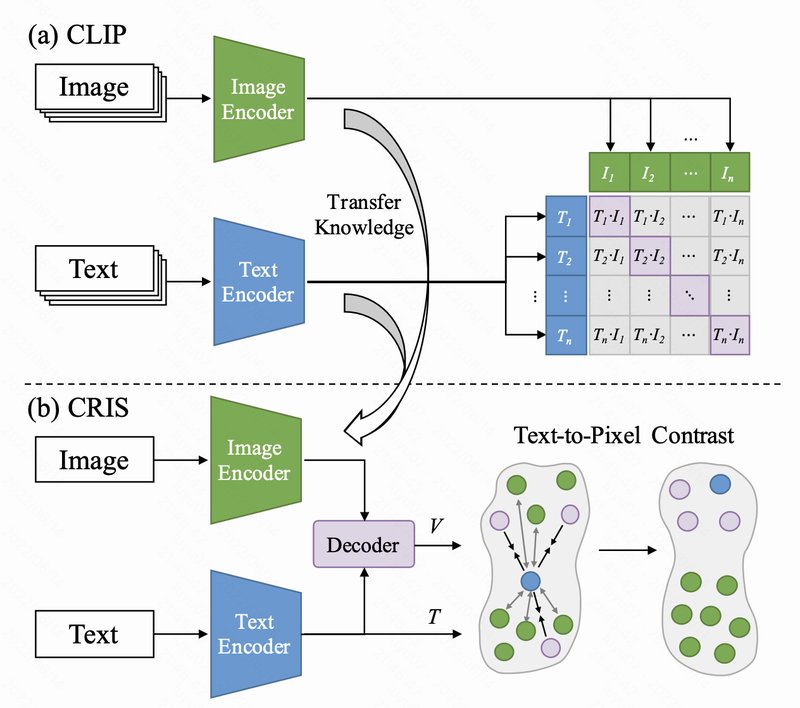
CRIS: CLIP-Driven Referring Image Segmentation
Zhaoqing Wang*, Yu Lu*, Qiang Li, Xunqiang Tao, Yandong Guo, MingMing Gong, Tongliang Liu
CVPR 2022
[Paper] [Code]